Model fit
Which machine runs which model
Memory decides which models fit. Pick a model size and quality, and see every machine and card we sell that can hold it.
30–34B at 4-bit
About 20 GB of GPU memory
The sweet spot for many people: noticeably smarter answers, and still a single 24–32 GB card at 4-bit.
Examples: Gemma 2 27B, Qwen2.5 32B
13 of 21 machines and cards can run it
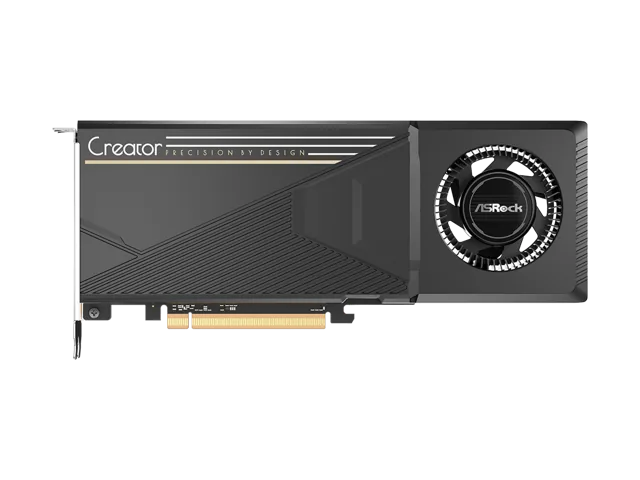 ASRock Intel Arc Pro B60 Creator 24GB24 GB£499
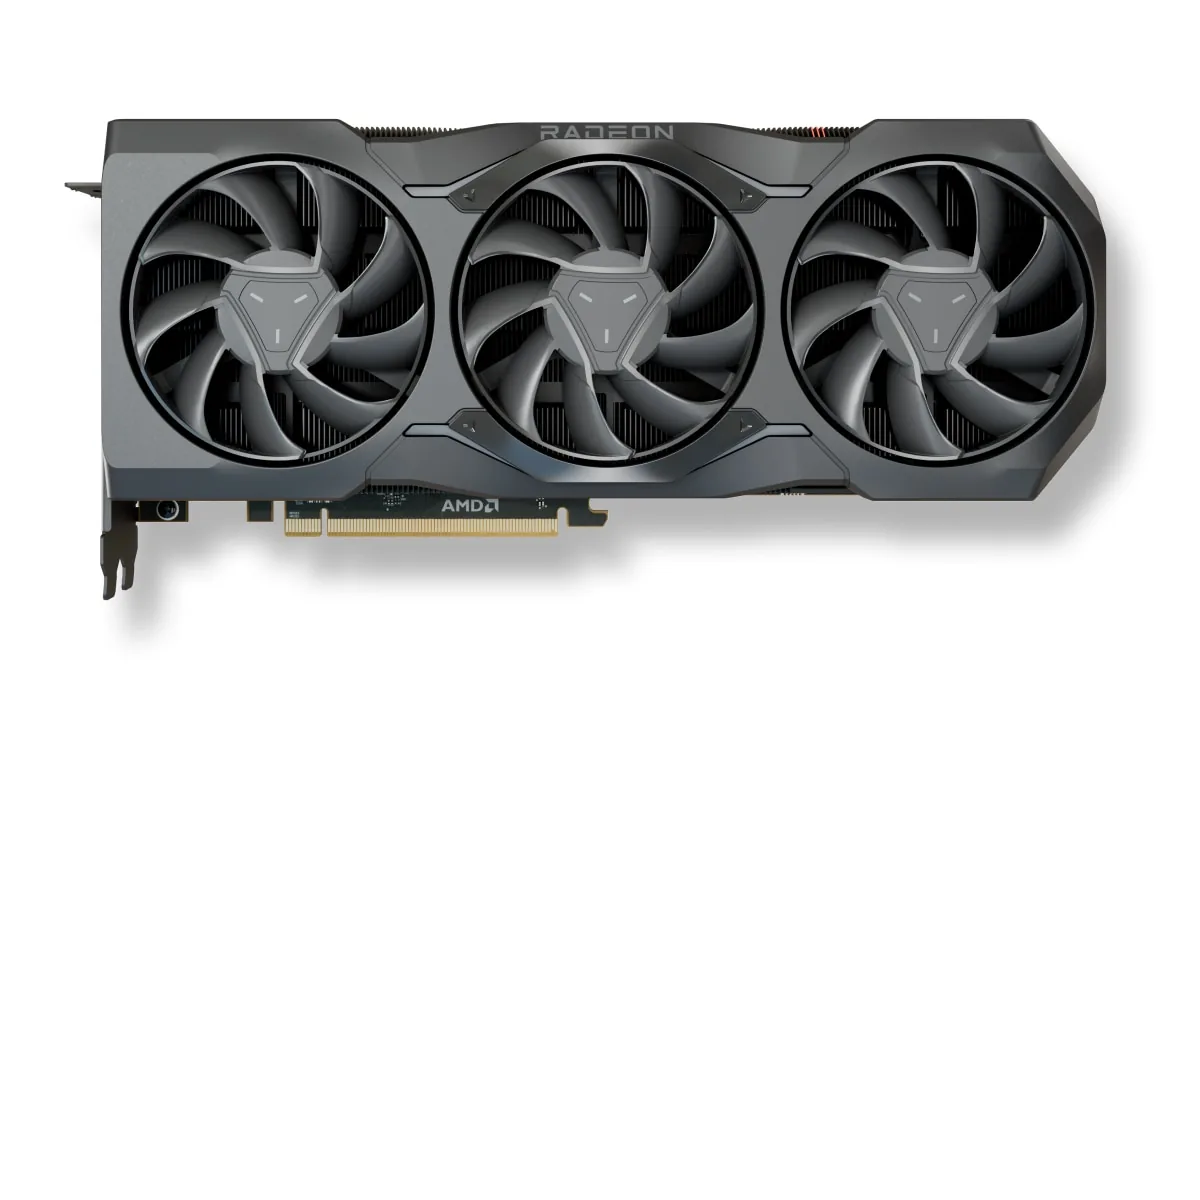 SAPPHIRE PULSE AMD Radeon RX 7900 XTX 24GB24 GB£749
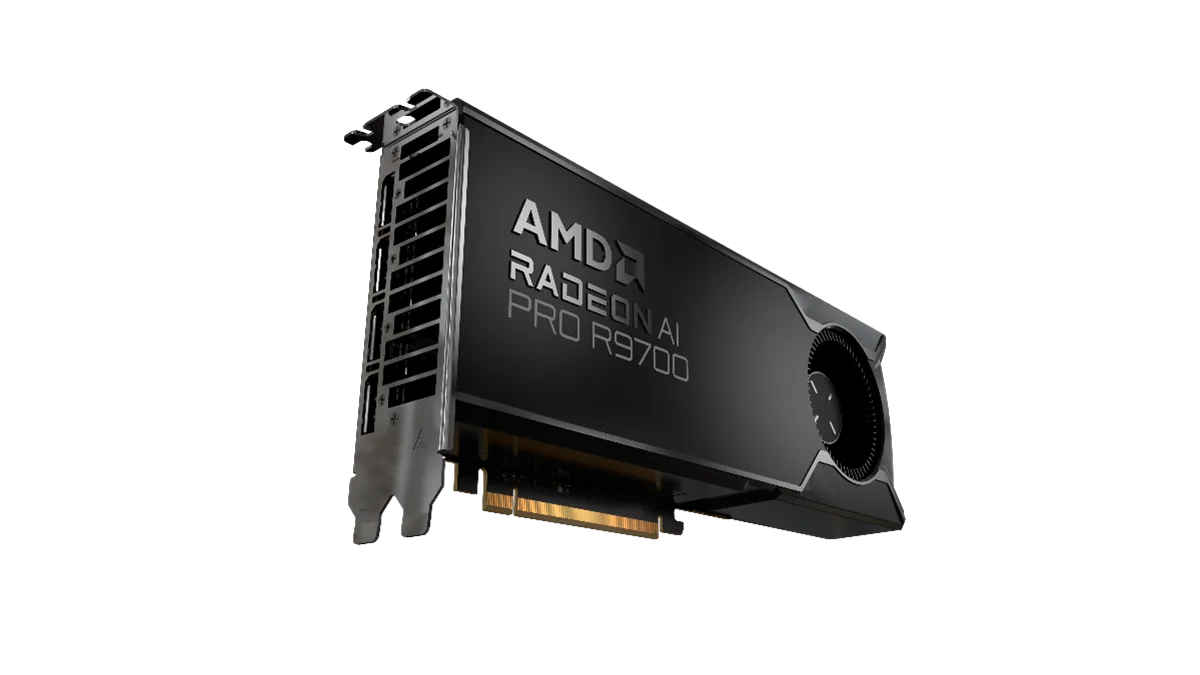 PowerColor AMD Radeon AI PRO R9700 32GB32 GB£1,089
 Tenstorrent Wormhole n300s24 GB£1,169
 Tenstorrent Blackhole p150a32 GB£1,169
 NVIDIA GeForce RTX 409024 GB£1,339
 NVIDIA GeForce RTX 509032 GB£1,669
 Minisforum MS-S1 Max128 GB unified£2,059
 AMD Radeon PRO W7900 (48 GB)48 GB£2,999
 Apple Mac Studio (M3 Ultra)96 GB unified£3,339
 Beelink GTR9 Pro128 GB unified£3,639
 NVIDIA DGX Spark128 GB unified£3,929
 NVIDIA RTX PRO 6000 Blackwell Workstation Edition (96 GB)96 GB£11,079
All numbers are approximate. We count about (parameters × bits ÷ 8) for the weights plus 20–30% for context and buffers, then treat 90% of a graphics card's memory and 75% of a unified-memory system's memory as usable. Long contexts, image models and batching need more. One card is counted on its own; several cards can be combined in one machine.
Not sure which one?
Tell the assistant what you want to run and your budget.