Shop by use
Local LLM hardware: which machine runs which model
Local LLM hardware for language and image models: private, offline and with no monthly bill.
Buying tip: Memory decides which models fit. Speed comes second. Check the model size first, then pick the machine.
Memory decides which models you can run; speed comes second. About 6 GB holds a 7–8B model at 4-bit, about 42 GB a 70B model and about 80 GB a 120B-class model, so start from the largest model you want and pick a machine with enough usable memory. Then choose the software platform: CUDA on NVIDIA, Metal and MLX on a Mac, or ROCm and Vulkan on AMD.
Our picks
70B and 120B-class models in one small box
Ryzen AI Max+ 395
Beelink
Beelink GTR9 Pro
- 128 GB unified
- AMD Ryzen AI Max+ 395
Runs up to 120B+ at 4-bit
On Windows the GPU can be given up to 96 GB of the 128 GB. Check that the model you plan to run fits in that before you buy.
£3,639128 GB of unified memory, about 96 GB for models, on Windows or Linux; plan for Linux to give the GPU the most memory.
Fastest speed on models up to 30B
GeForce RTX 5090
NVIDIA
NVIDIA GeForce RTX 5090
- 32 GB
- NVIDIA Blackwell (GB202)
Runs up to 30–34B at 4-bit
32 GB runs 30B-class models comfortably at 4-bit, but a 70B model will not fit on one card. For 70B, plan for two cards or a large unified-memory system.
£1,66932 GB of GDDR7 at 1,792 GB/s with CUDA. It will not hold a 70B model on one card.
Large models, near silent
Mac Studio M3 Ultra
Apple
Apple Mac Studio (M3 Ultra)
- 96 GB unified
- 60-core; 80-core option
Runs up to 70B at 4-bit
macOS keeps part of the unified memory for the system, so plan for the GPU to use most of it, not all. Size the configuration with some headroom above the model.
£3,33996 GB as standard and 819 GB/s, so a 70B model at 4-bit runs quickly while the machine stays close to silent.
NVIDIA
NVIDIA GeForce RTX 5090
- 32 GB
- NVIDIA Blackwell (GB202)
Runs up to 30–34B at 4-bit
32 GB runs 30B-class models comfortably at 4-bit, but a 70B model will not fit on one card. For 70B, plan for two cards or a large unified-memory system.
£1,669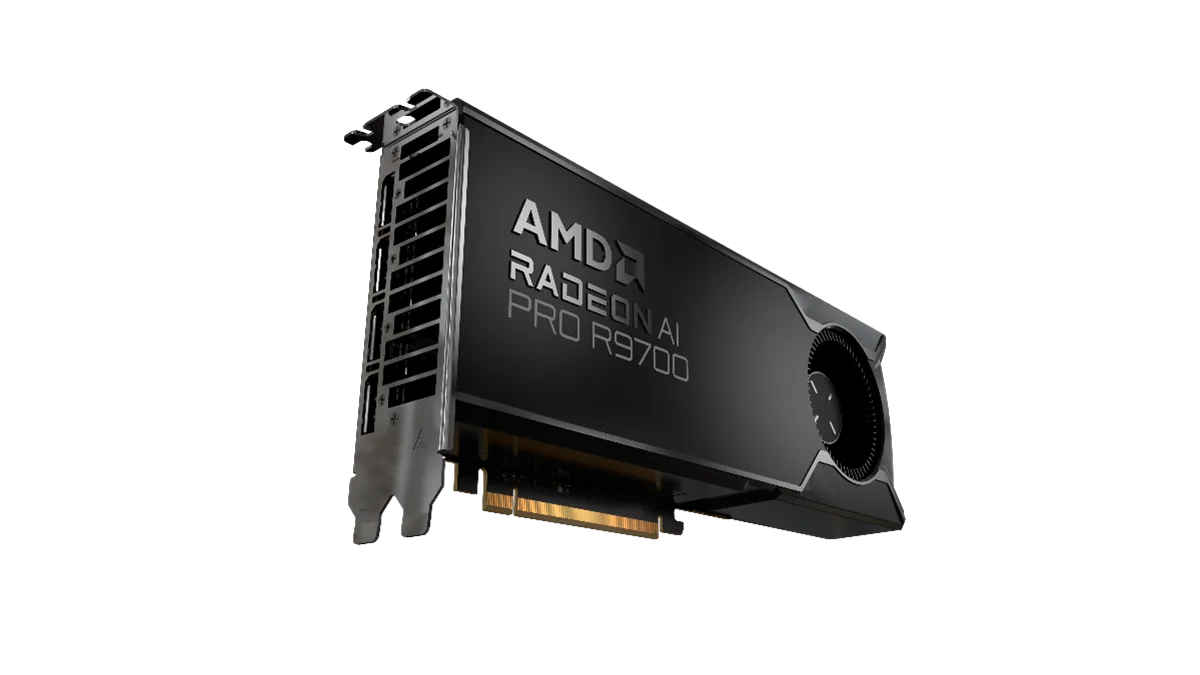
PowerColor
PowerColor AMD Radeon AI PRO R9700 32GB
- 32 GB
- AMD RDNA 4 (Navi 48)
Runs up to 30–34B at 4-bit
Check that your tools support ROCm on your operating system before buying. PyTorch and llama.cpp do; some niche tools still assume CUDA.
£1,089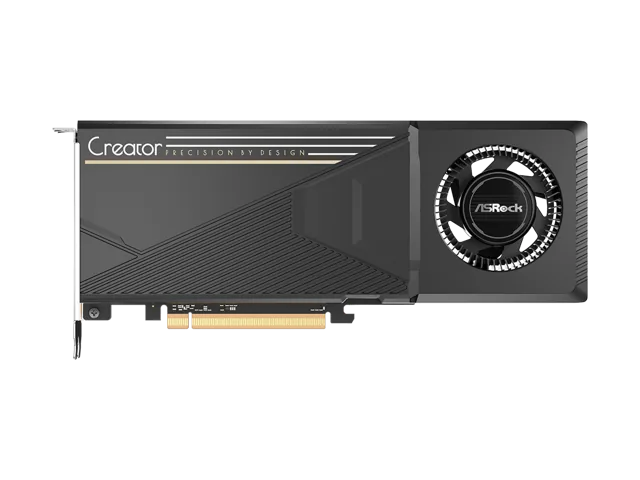
ASRock
ASRock Intel Arc Pro B60 Creator 24GB
- 24 GB
- Intel Xe2 (Battlemage)
Runs up to 30–34B at 4-bit
This is a single-GPU card with 24 GB. It uses a PCIe 5.0 slot wired at x8 and also works in PCIe 4.0 slots; check ASRock's spec sheet for the exact length and power connector before you order.
£499Beelink
Beelink GTR9 Pro
- 128 GB unified
- AMD Ryzen AI Max+ 395
Runs up to 120B+ at 4-bit
On Windows the GPU can be given up to 96 GB of the 128 GB. Check that the model you plan to run fits in that before you buy.
£3,639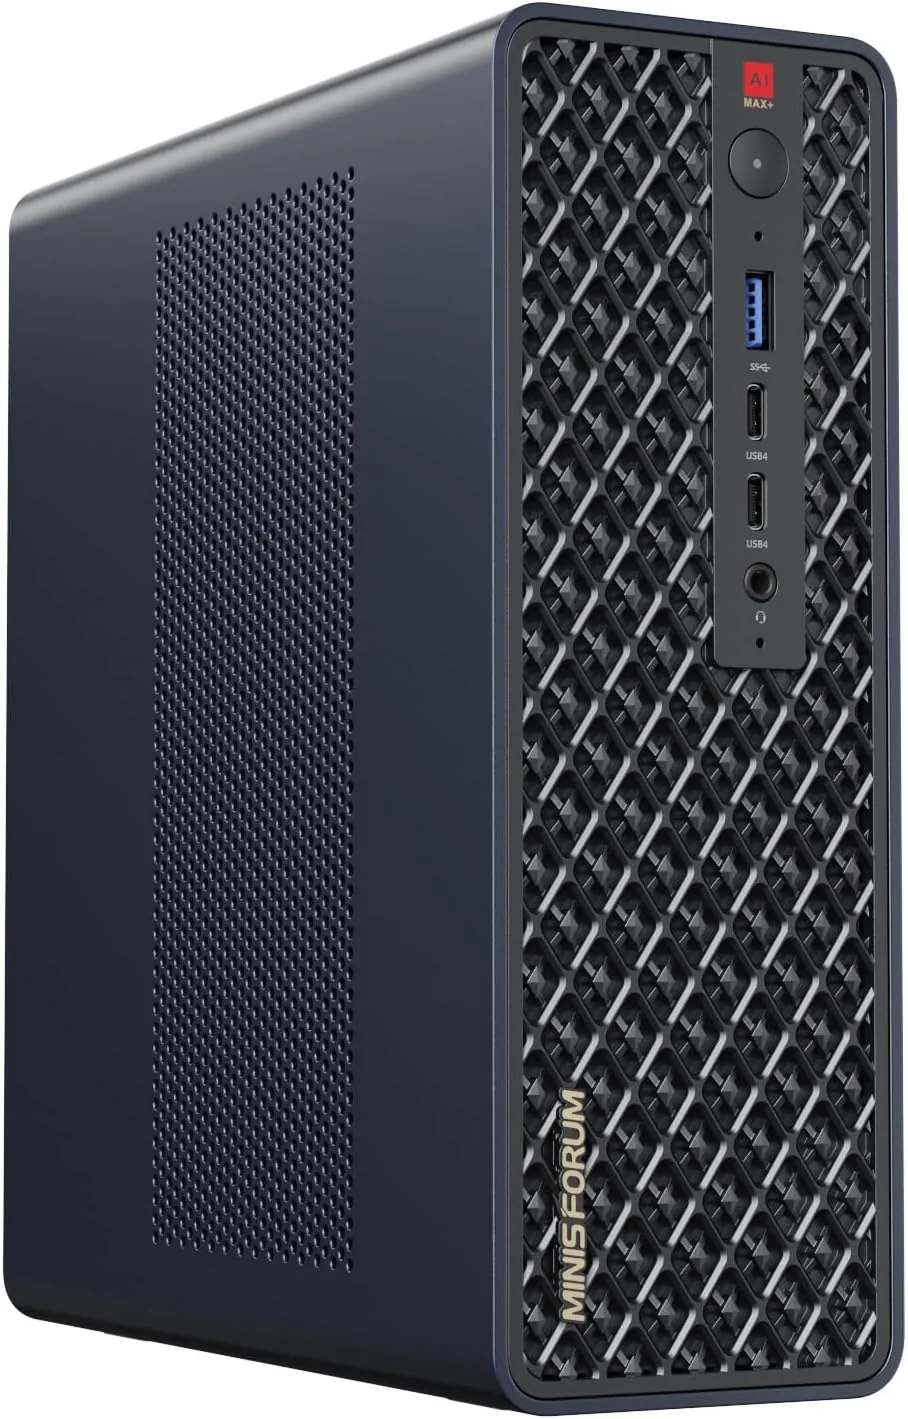
Minisforum
Minisforum MS-S1 Max
- 128 GB unified
- AMD Ryzen AI Max+ 395
Runs up to 120B+ at 4-bit
The PCIe slot takes low-profile cards and runs at x4 lanes. It is ideal for a faster network card, not for adding a full-size graphics card.
£2,059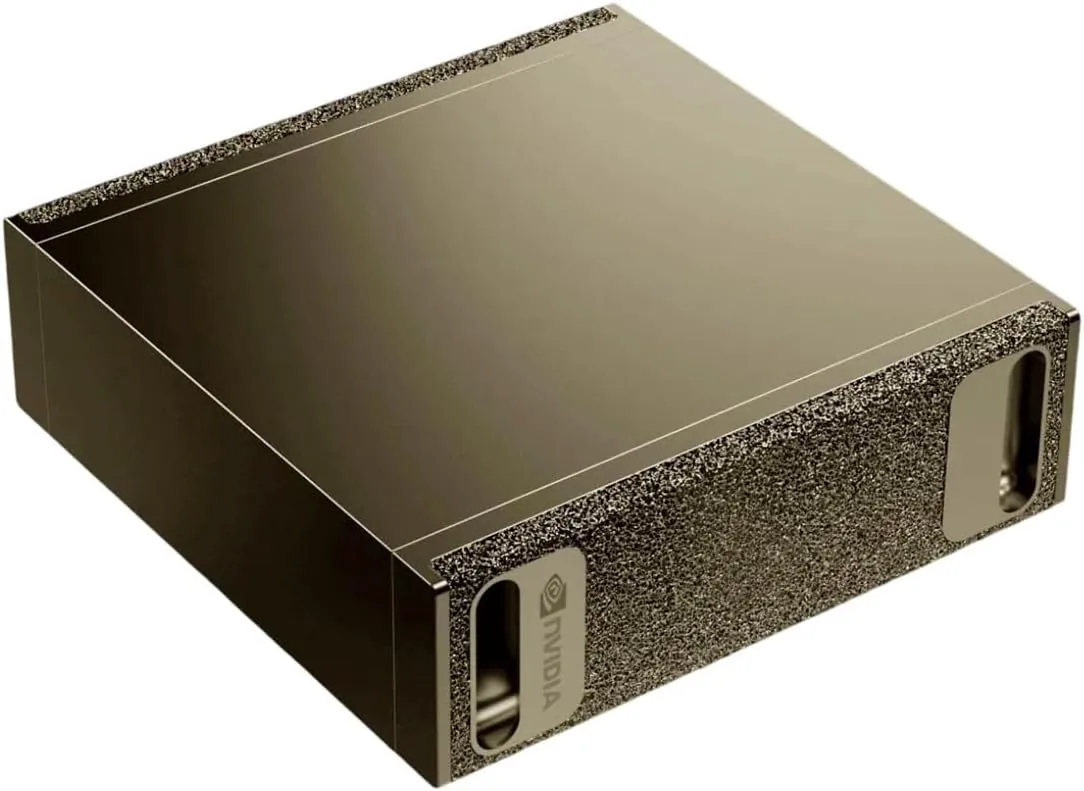
NVIDIA
NVIDIA DGX Spark
- 128 GB unified
- NVIDIA GB10 Grace Blackwell
Runs up to 120B+ at 4-bit
Its memory bandwidth (273 GB/s) is lower than a high-end graphics card's, so large dense models generate text more slowly than they would on an RTX 5090. Its strengths are capacity and the CUDA software stack.
£3,929Apple
Apple Mac Studio (M3 Ultra)
- 96 GB unified
- 60-core; 80-core option
Runs up to 70B at 4-bit
macOS keeps part of the unified memory for the system, so plan for the GPU to use most of it, not all. Size the configuration with some headroom above the model.
£3,339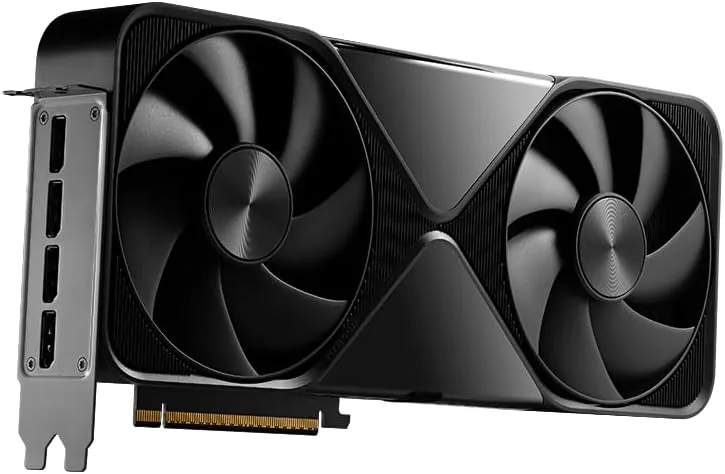
NVIDIA
NVIDIA RTX PRO 6000 Blackwell Workstation Edition (96 GB)
- 96 GB
- NVIDIA Blackwell (GB202)
Runs up to 120B+ at 4-bit
This is the 600 W Workstation Edition with a double flow-through cooler. It needs a 16-pin power cable, a case that takes a 12-inch card and good airflow.
£11,079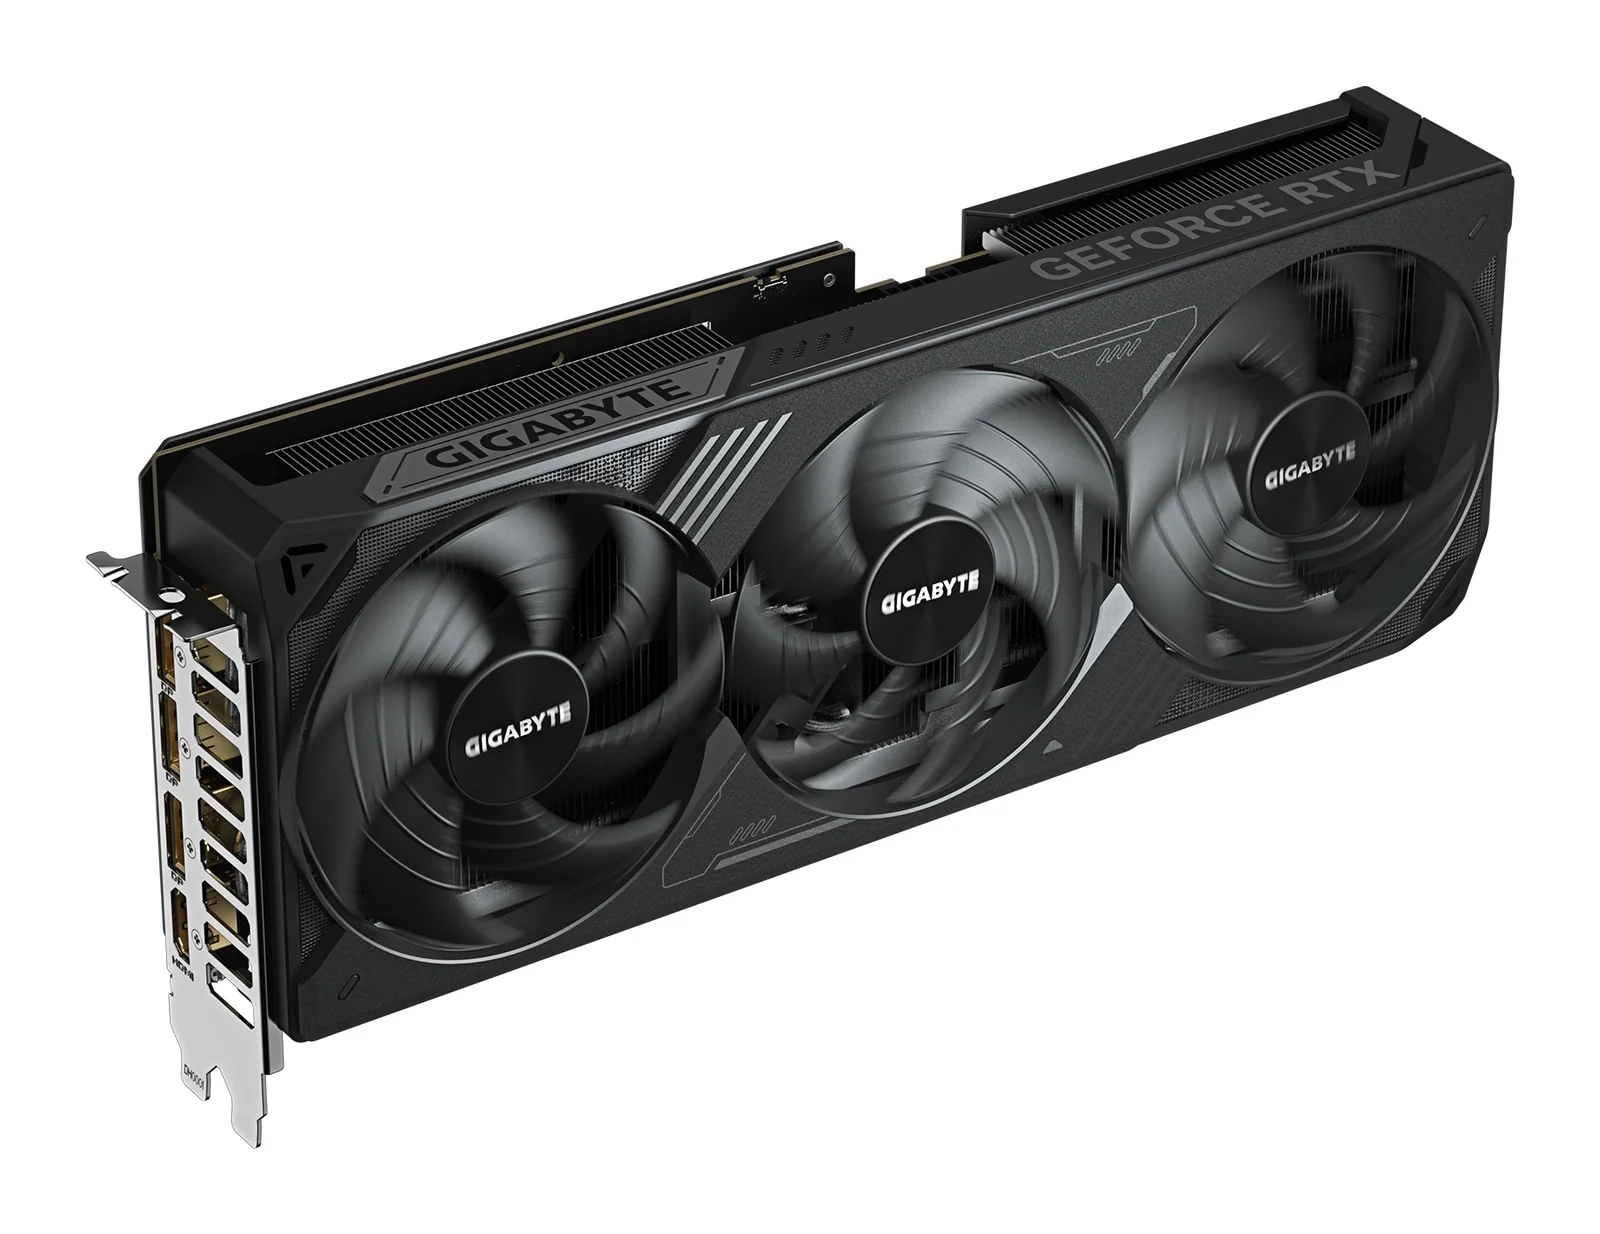
GIGABYTE
GIGABYTE GeForce RTX 5070 Ti WINDFORCE OC SFF 16G
- 16 GB
- NVIDIA GeForce RTX 5070 Ti (Blackwell)
Runs up to 13–14B at 4-bit
It needs one 16-pin power cable or the adapter in the box, which takes two 8-pin PCIe cables. GIGABYTE recommends a 750 W power supply.
£709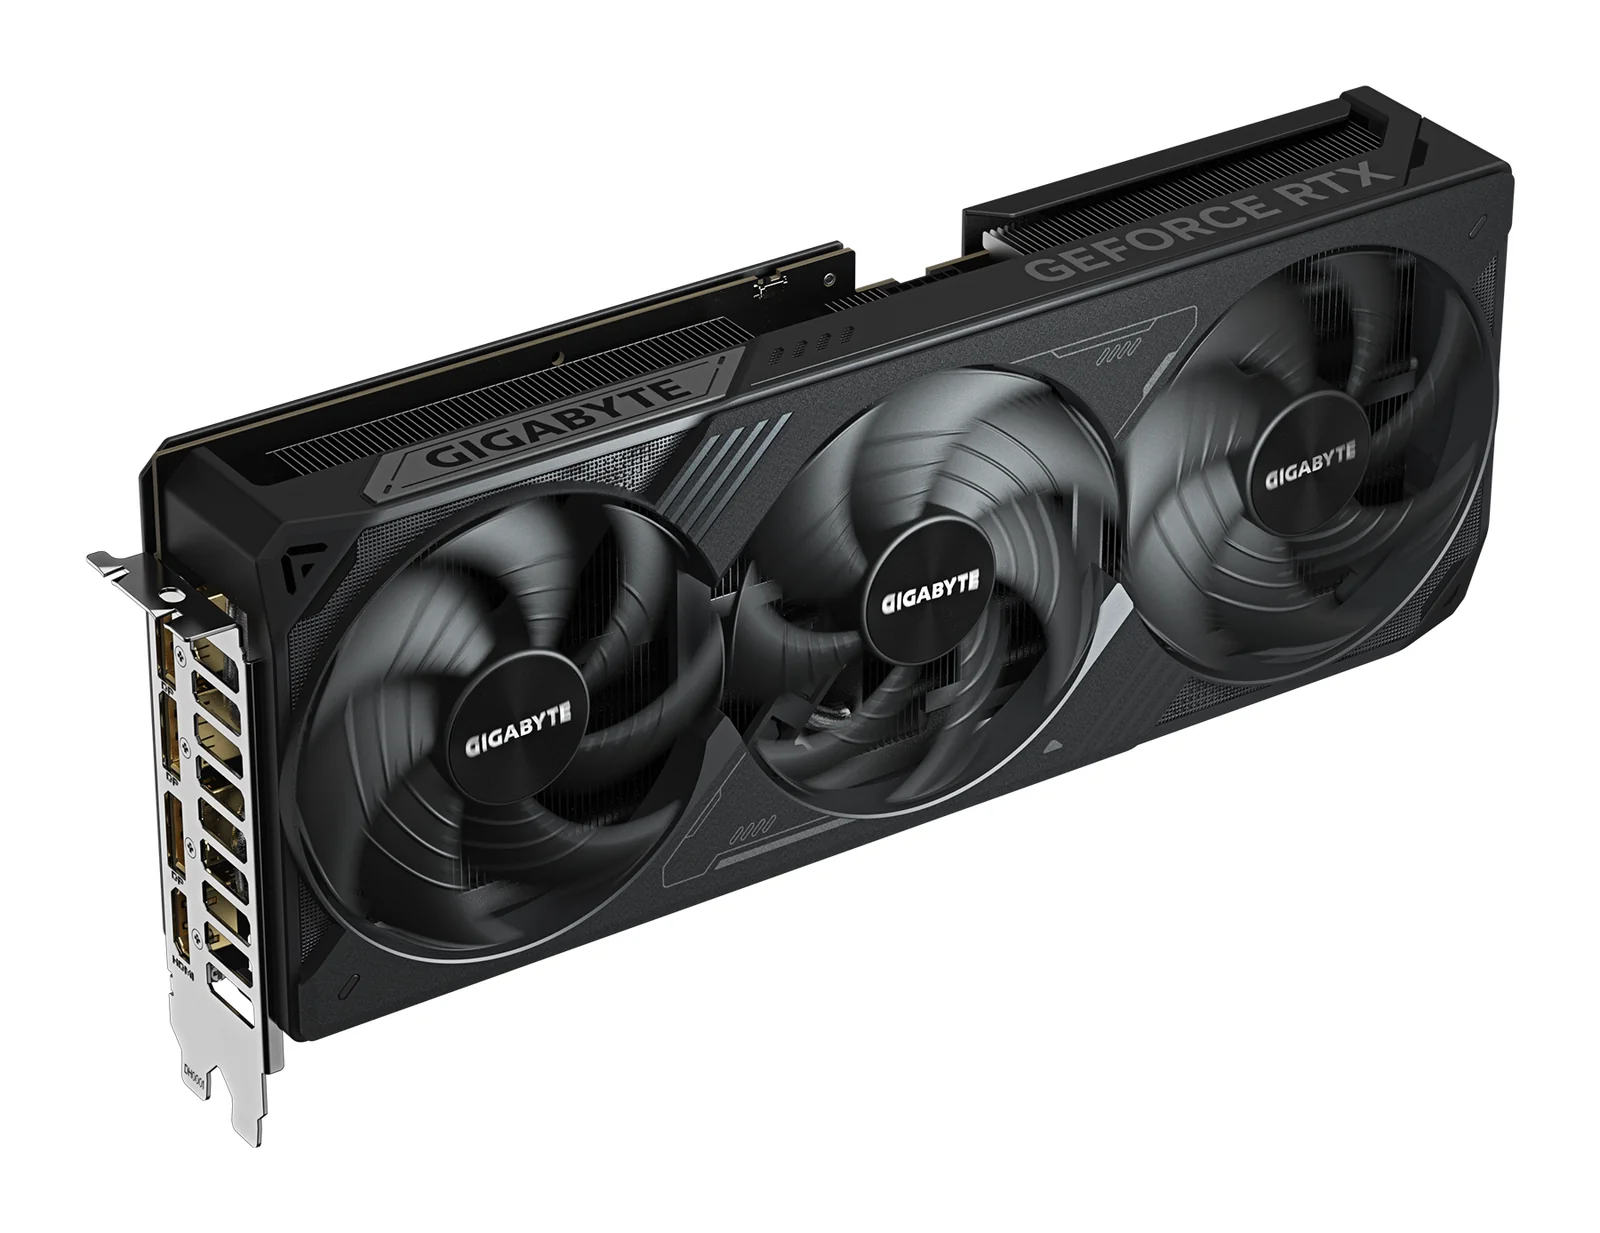
GIGABYTE
GIGABYTE GeForce RTX 5080 WINDFORCE OC SFF 16G
- 16 GB
- NVIDIA GeForce RTX 5080 (Blackwell)
Runs up to 13–14B at 4-bit
It has the same 16 GB as the RTX 5070 Ti, so it does not fit larger AI models; it runs them faster. For more memory on one card, look at the RTX 5090 or a 24 to 32 GB card.
£899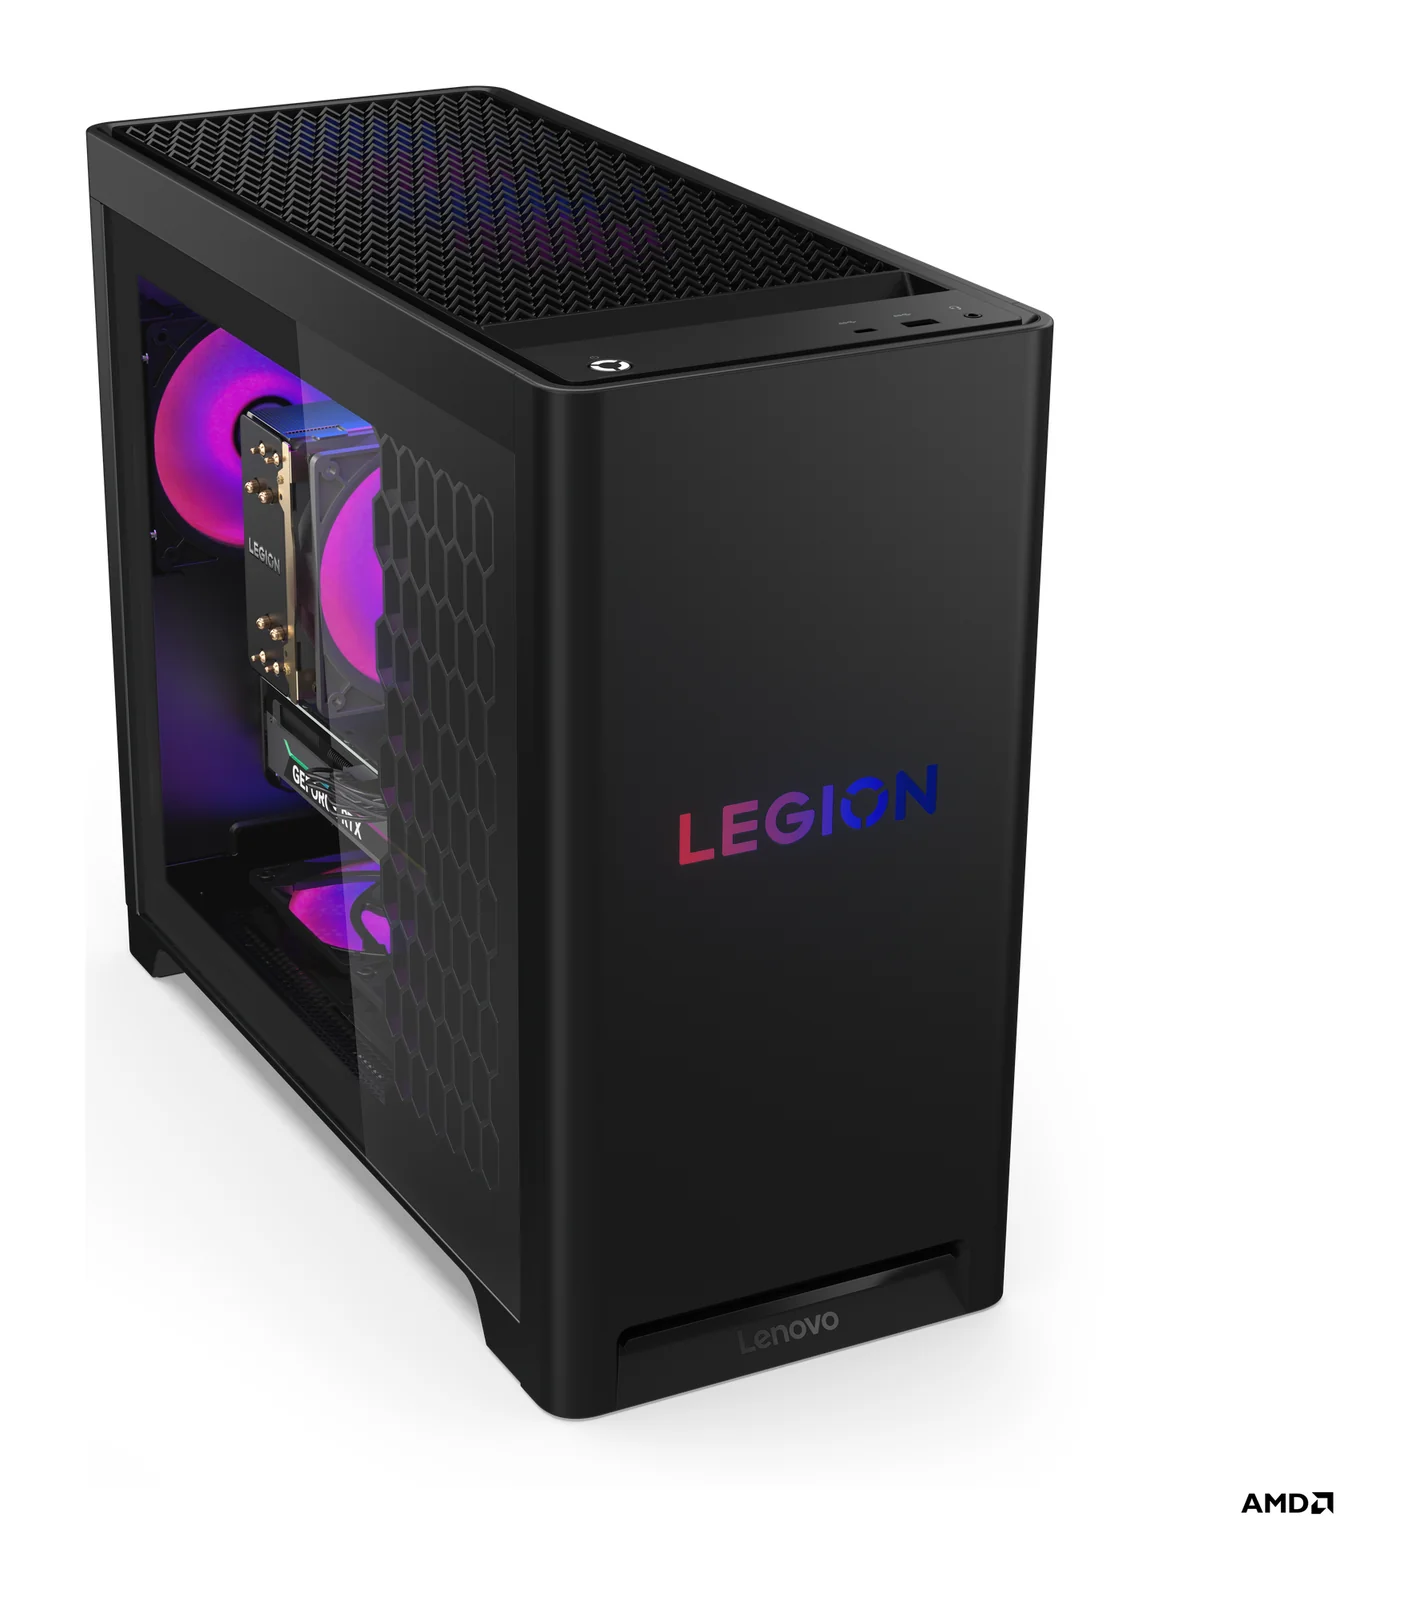
Lenovo
Lenovo Legion Tower 5 Gen 10 (RTX 5070 Ti)
- 32 GB
- AMD Ryzen 7 7800X3D (8 cores / 16 threads, 4.2 / 5.0 GHz, 96 MB L3)
The system memory is two 16 GB modules, and Lenovo lists 32 GB as the maximum for this tower, so plan on 32 GB for its life. Storage has room to grow: three M.2 slots and a 3.5-inch bay.
£1,809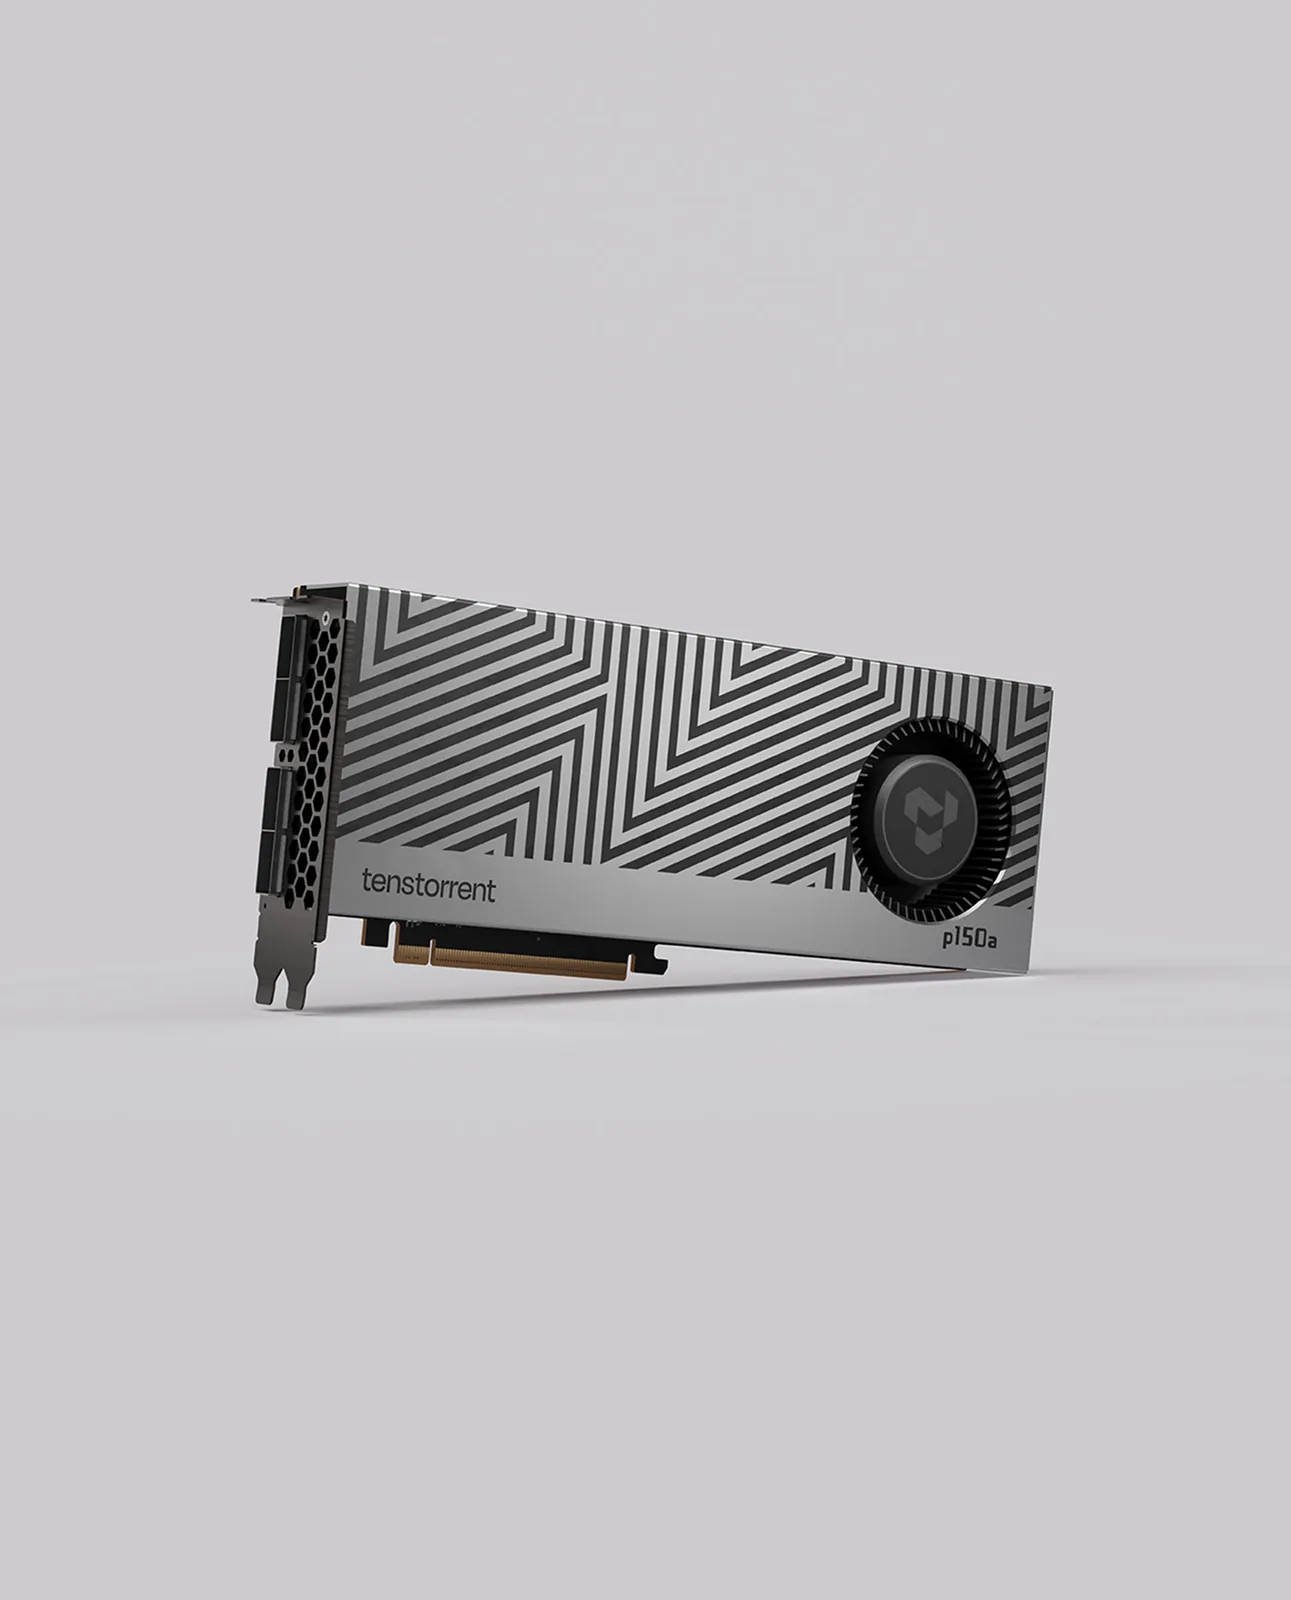
Tenstorrent
Tenstorrent Blackhole p150a
- 32 GB
- Tenstorrent Blackhole
Runs up to 30–34B at 4-bit
This is not a CUDA card. Check that the models you need are supported in Tenstorrent's open-source model library before you buy.
£1,169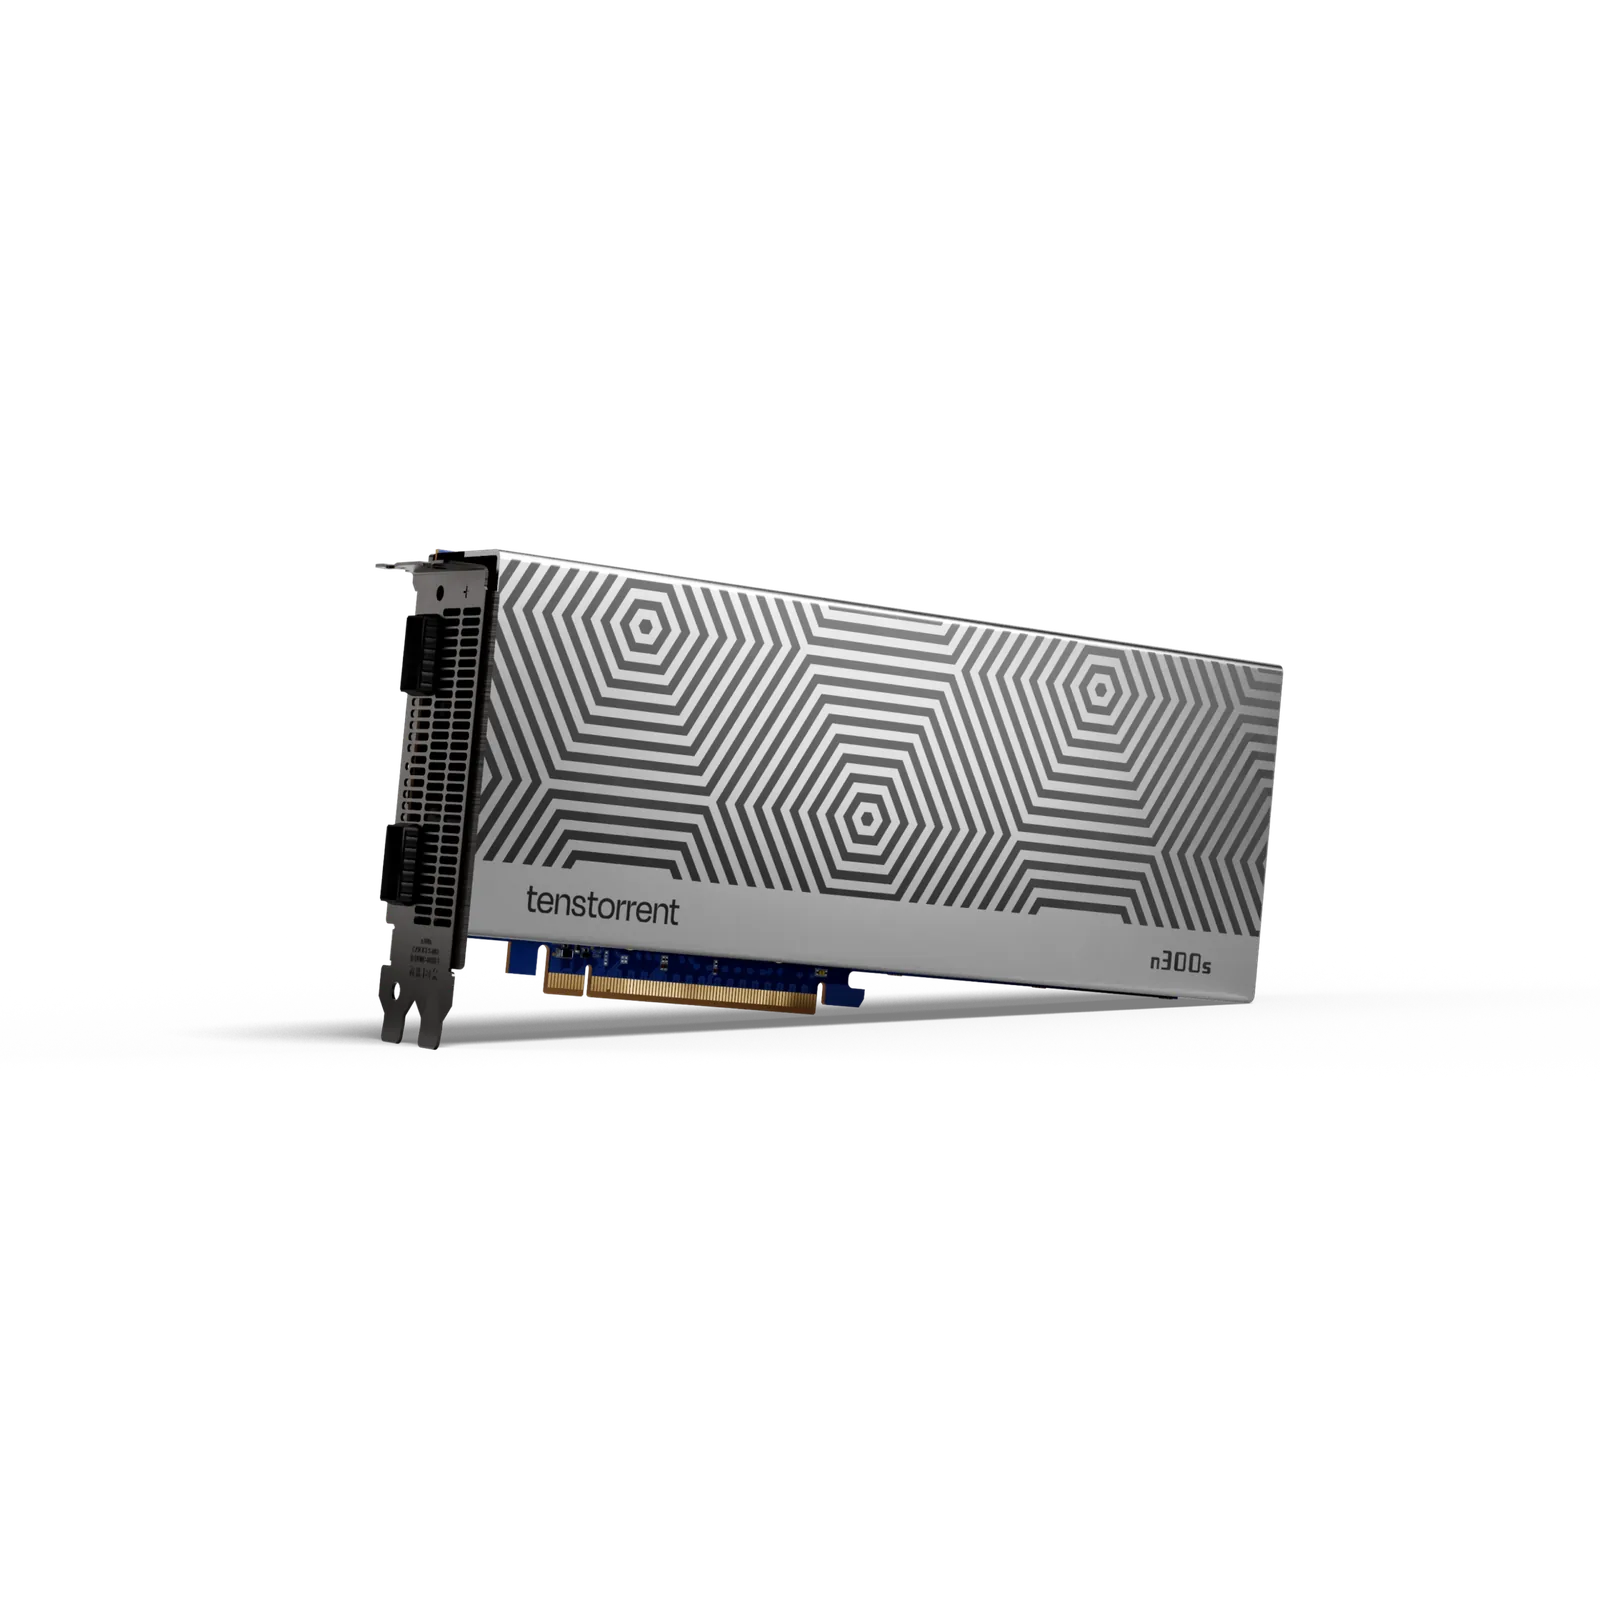
Tenstorrent
Tenstorrent Wormhole n300s
- 24 GB
Runs up to 30–34B at 4-bit
The 24 GB is split across two chips (12 GB each), so larger models have to be spread across both. Check that the model you want has a working multi-chip version.
£1,169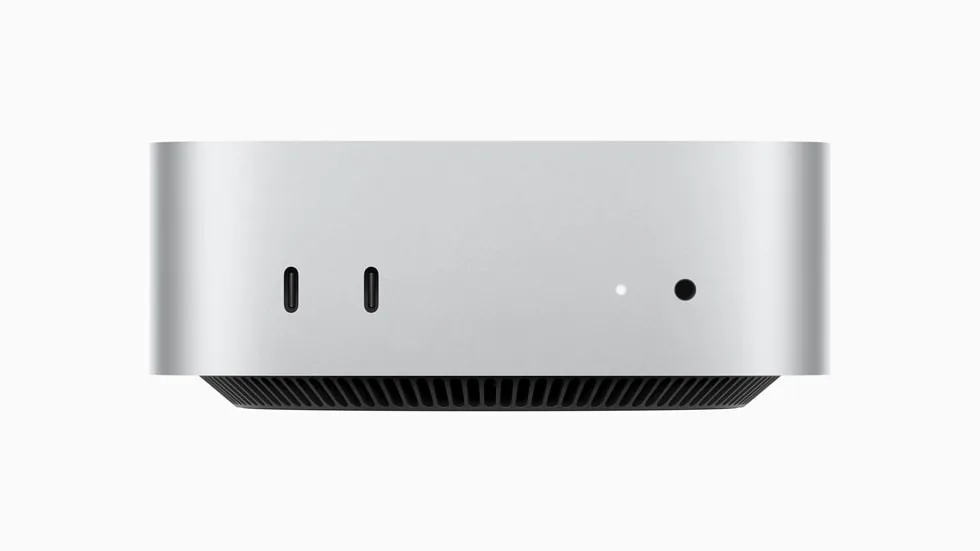
Apple
Apple Mac mini (M4 Pro)
- 24 GB unified
- 16-core; 20-core option
Runs up to 13–14B at 4-bit
Memory cannot be upgraded after purchase. If local AI is the goal, choose 48 GB or 64 GB now. With 24 GB, models above about 14B parameters are a squeeze.
£1,169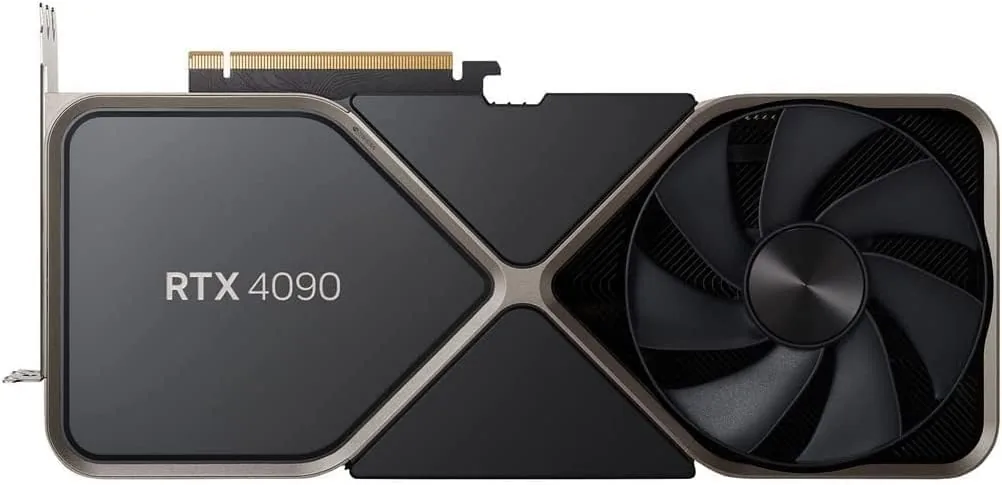
NVIDIA
NVIDIA GeForce RTX 4090
- 24 GB
- NVIDIA Ada Lovelace (AD102)
Runs up to 30–34B at 4-bit
Push the 16-pin power cable fully into the card and avoid sharp bends close to the plug. A loose connector is the most common cause of trouble with this card.
£1,339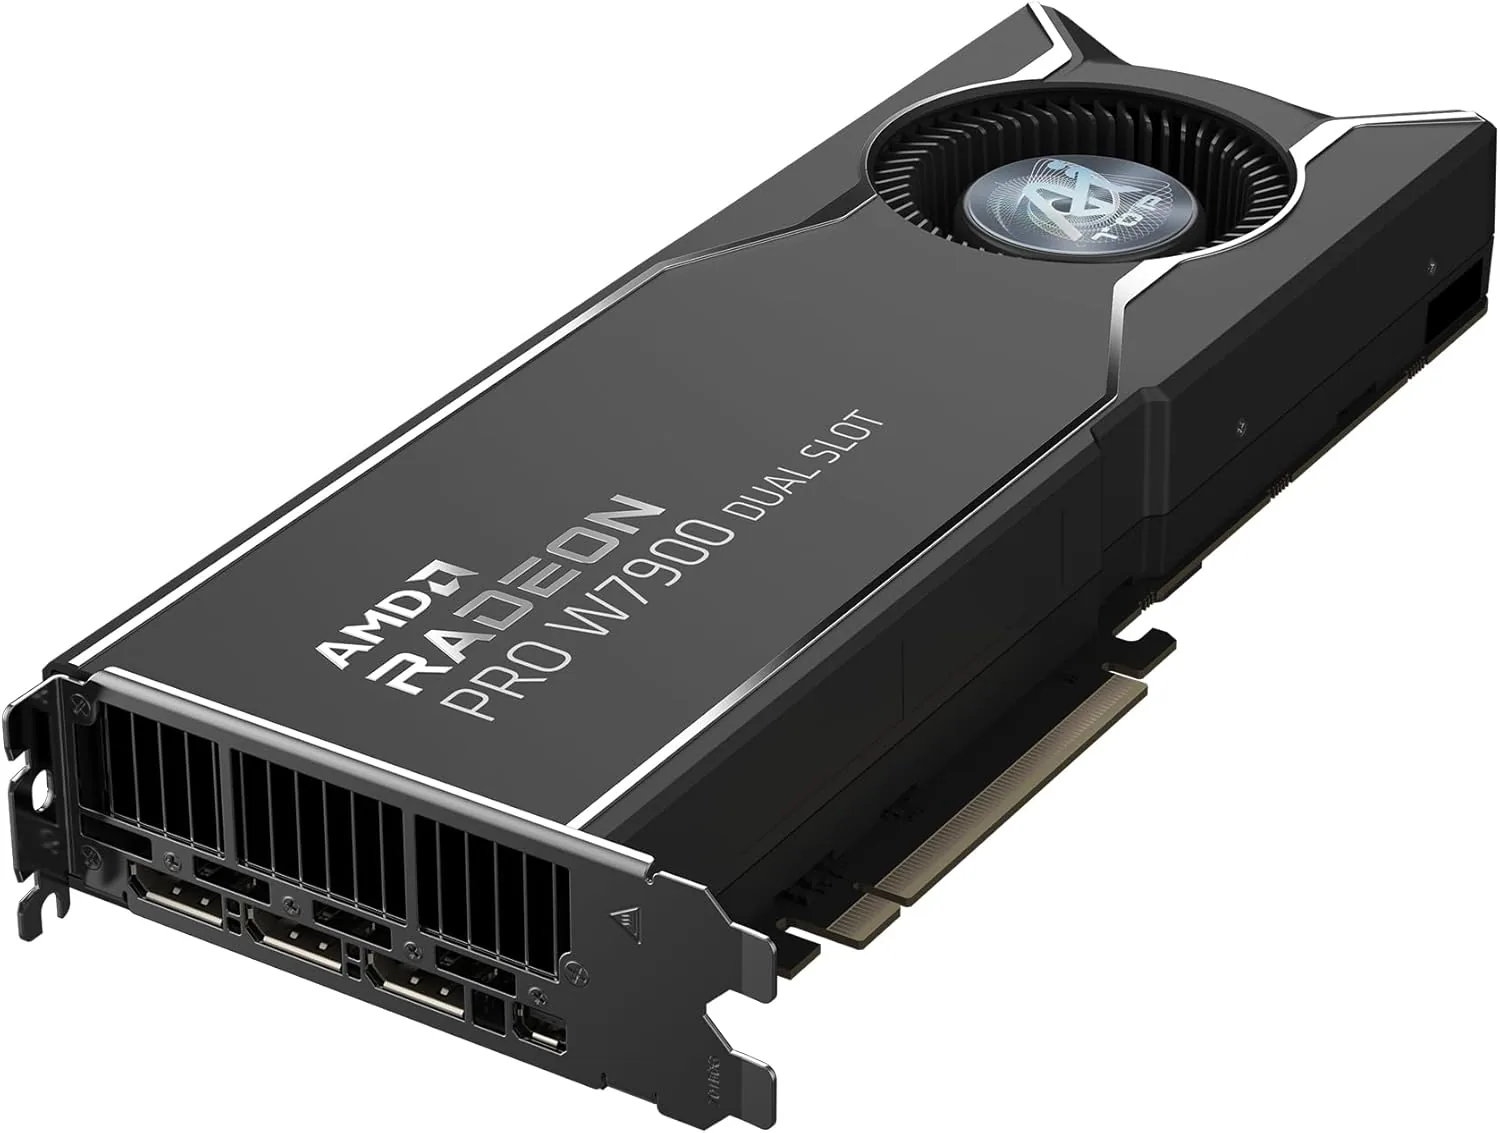
AMD
AMD Radeon PRO W7900 (48 GB)
- 48 GB
- AMD RDNA 3 (Navi 31)
Runs up to 70B at 4-bit
Choose the W7900 when model or scene size matters most. The newer R9700 has less memory (32 GB) but adds FP8 support and is faster per watt for AI.
£2,999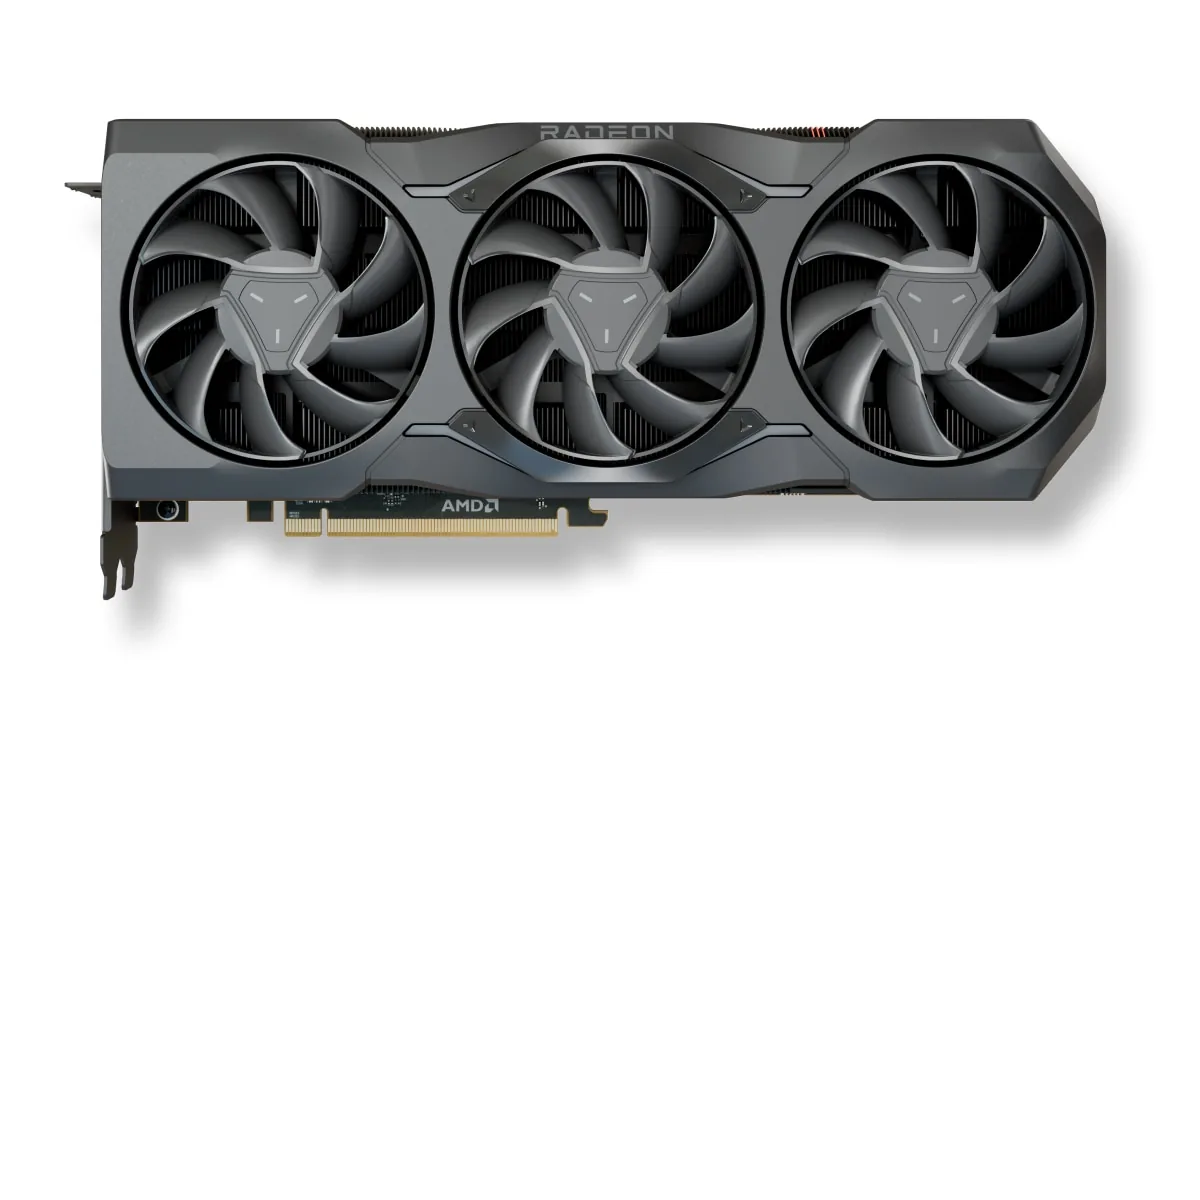
SAPPHIRE
SAPPHIRE PULSE AMD Radeon RX 7900 XTX 24GB
- 24 GB
- AMD RDNA 3 (Navi 31)
Runs up to 30–34B at 4-bit
The PULSE is 313 mm long and 2.7 slots thick, with three 8-pin power connectors. Measure your case and check your power supply (800 W minimum) before ordering.
£749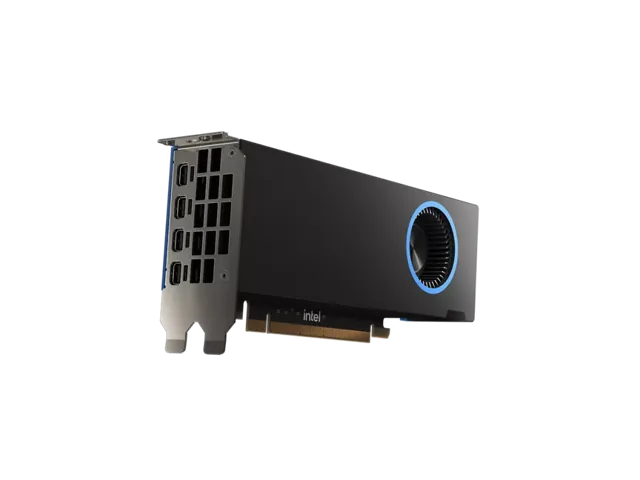
Intel
Intel Arc Pro B50
- 16 GB
- Intel Xe2 (Battlemage)
Runs up to 13–14B at 4-bit
No power cable is needed, so it suits small-form-factor machines. 16 GB runs 7B to 14B models at 4-bit; anything larger needs a bigger card.
£249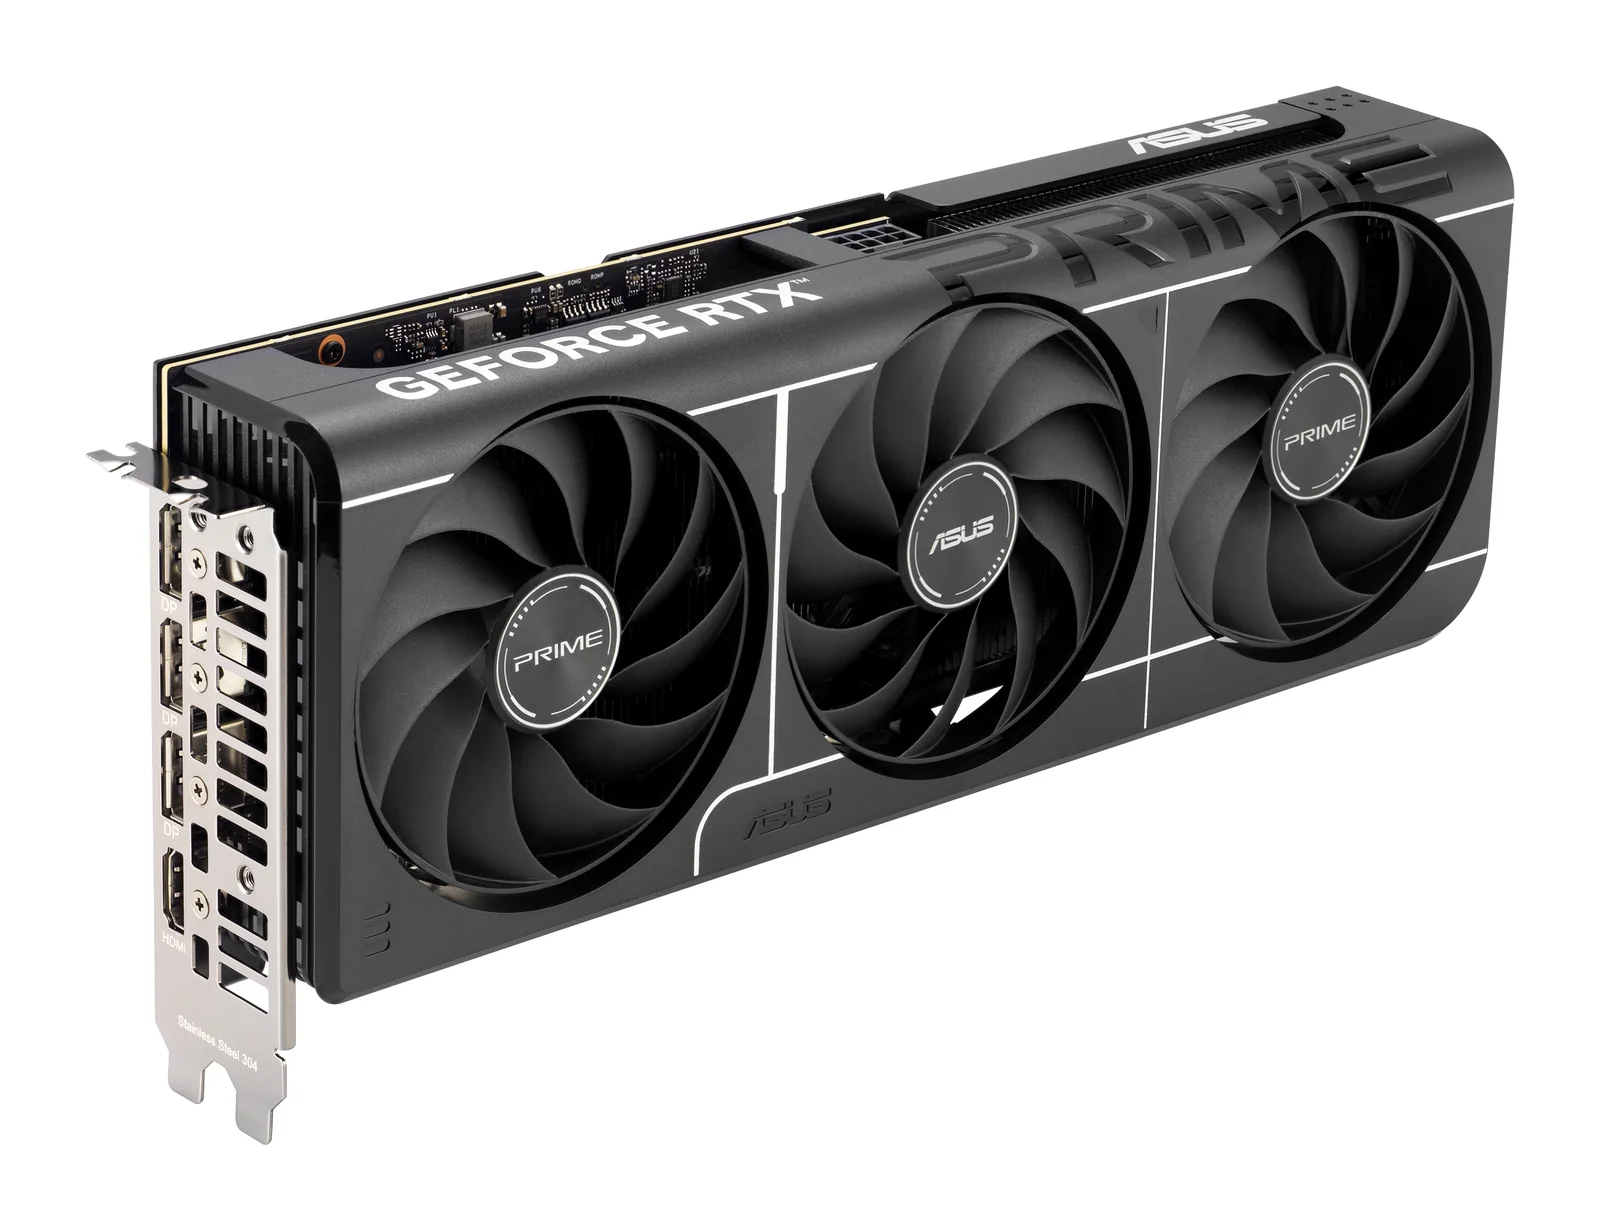
ASUS
ASUS Prime GeForce RTX 5060 Ti 16GB OC Edition
- 16 GB
- NVIDIA GeForce RTX 5060 Ti (Blackwell)
Runs up to 13–14B at 4-bit
Buy only the 16 GB version for local AI; this is the one. Its 128-bit memory bus is narrower than the bigger cards', so models generate text more slowly than on an RTX 5070 Ti.
£309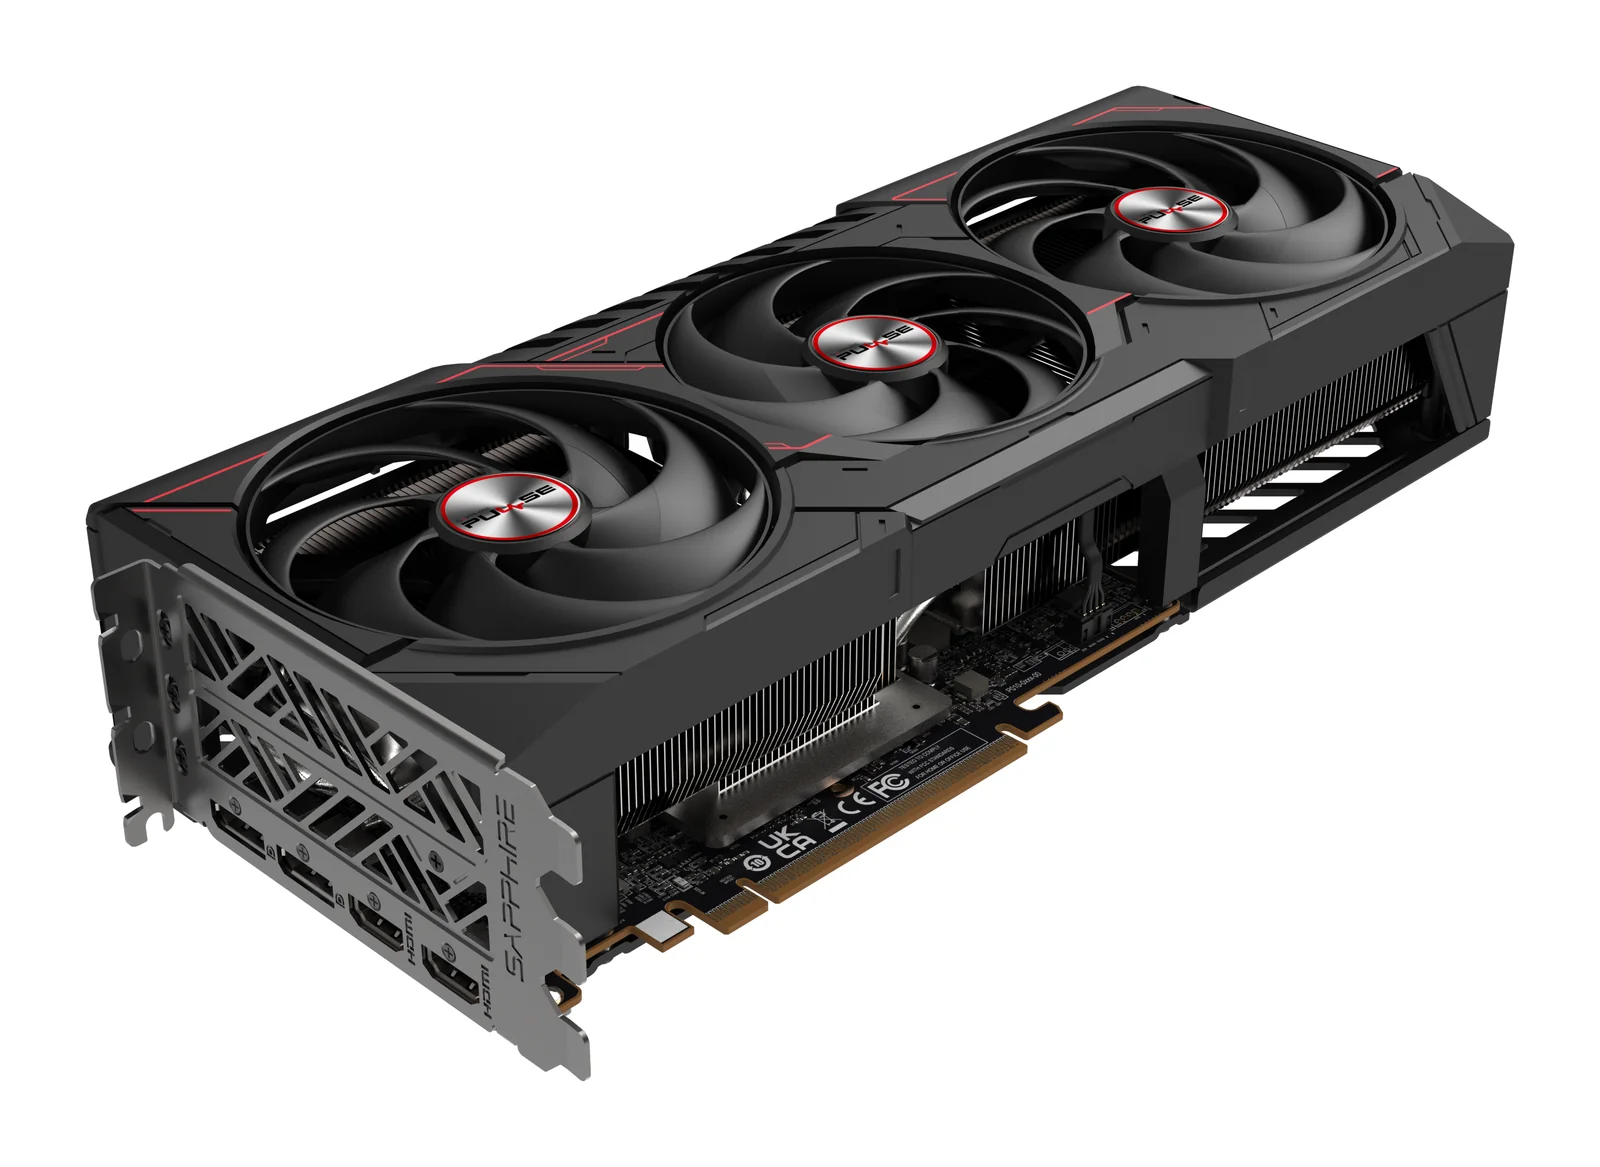
SAPPHIRE
SAPPHIRE PULSE AMD Radeon RX 9070 XT 16GB
- 16 GB
- AMD Radeon RX 9070 XT (RDNA 4)
Runs up to 13–14B at 4-bit
The card is 320 mm long and three slots thick, and it takes two 8-pin power cables. SAPPHIRE asks for at least a 750 W power supply, so measure the case first.
£439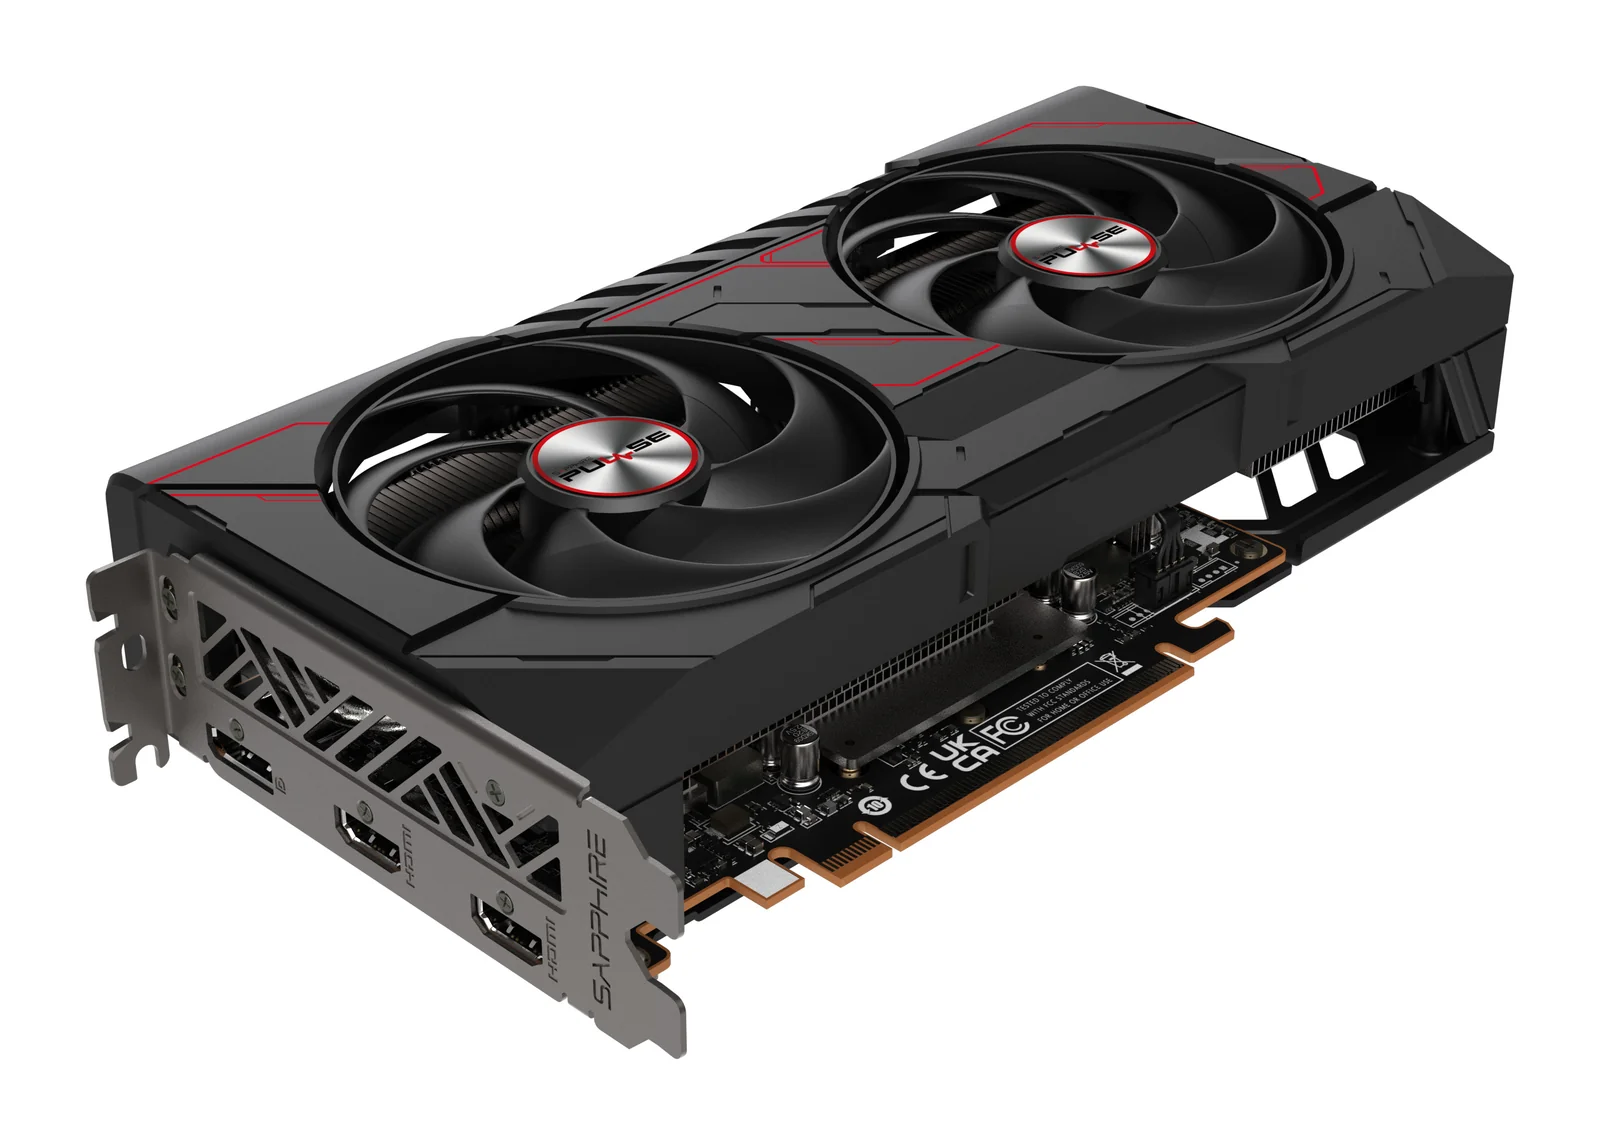
SAPPHIRE
SAPPHIRE PULSE AMD Radeon RX 9060 XT 16GB
- 16 GB
- AMD Radeon RX 9060 XT (RDNA 4)
Runs up to 13–14B at 4-bit
This is the 16 GB version; the 8 GB version is a different card and is already short of memory in new games. One 8-pin cable and a 450 W power supply are enough.
£249How to choose local AI hardware
- Count usable memory, not the label
- Our model guide treats 90% of a graphics card's memory as usable and 75% of unified memory, because the operating system keeps part of a shared pool. A 64 GB Mac gives about 48 GB to models; a 48 GB card about 43 GB.
- Match memory to model size
- Up to 14B at 4-bit: a 16 GB card or a 24 GB Mac mini. 30B-class at 4-bit: one 24 GB or 32 GB card. 70B at 4-bit: a 48 GB card, two 24 GB cards or 64 GB+ of unified memory. 70B at 8-bit and 120B-class at 4-bit: a 96 GB card or a 128 GB unified-memory machine.
- Pick the platform your tools need
- NVIDIA if your tools need CUDA or you also game. A Mac Studio for large models in a near-silent box. A Ryzen AI Max+ mini PC for 128 GB on Windows or Linux. The DGX Spark if you build on CUDA and deploy to bigger NVIDIA systems.
- Bandwidth decides speed once it fits
- Each new token reads through the weights, so a model writes faster on a machine with more memory bandwidth: 1,792 GB/s on the RTX 5090, 819 GB/s on the Mac Studio, 273 GB/s on the Mac mini M4 Pro and the DGX Spark.
- When a cheaper machine is enough
- Chat, summaries, code completion and searching your own documents all work on 7B to 14B models, which fit in 16 GB. The Arc Pro B50 or a Mac mini with 24 GB covers that. Leave headroom if you work with long documents.
Questions people ask
Can I run a 70B model on one graphics card?
Only on a card with 48 GB or more. The Radeon PRO W7900 (48 GB) just holds it at 4-bit, and the RTX PRO 6000 (96 GB) holds it at 8-bit. A 32 GB card such as the RTX 5090 does not.
What do 4-bit and 8-bit mean for the hardware I need?
4-bit stores the model in about half the memory of 8-bit, with a small loss in quality, and it is how most people run models at home. 8-bit keeps more quality and needs roughly twice the memory, which is worth it for coding or exact data extraction.
How much extra memory do long chats and documents need?
The context memory grows with every token the model keeps in view, so plan above the model's own size. Choose the next memory size up rather than one that only just holds the model.
Is local AI hardware good for fine-tuning?
Fine-tuning needs more memory than running a model. Parameter-efficient methods such as LoRA cut that need sharply; for CUDA-based work, the 128 GB DGX Spark gives room at sizes a 32 GB card cannot reach.
Can you build a machine for the models I want to run?
Yes. Send a custom build request with the models you want to run, your budget and your country, and we will reply with a configuration and a quote.
Related pages: Graphics cards · Mini PCs · Apple · AI accelerators
Guides
Local AI · 5 min read
How Much Memory Do You Need to Run a Local LLM?
How much memory a local LLM needs: 7B to 120B+ models at 4-bit and 8-bit, how unified memory differs from VRAM, and which machines hold each size.
Read the guide →Local AI · 5 min read
Mac vs NVIDIA vs Ryzen AI Max+ for Local AI
Which platform fits which work: CUDA on NVIDIA, unified memory on a Mac, or 128 GB on a Ryzen AI Max+ mini PC. Memory, software and trade-offs.
Read the guide →Graphics cards · 5 min read
Choosing a GPU for Local AI: RTX 5090, R9700, B60
Choose a GPU for local AI by memory, software and bandwidth: RTX 5090, Radeon AI PRO R9700, Arc Pro B60 and the 48 GB and 96 GB workstation cards.
Read the guide →